01
Inspect the full record path
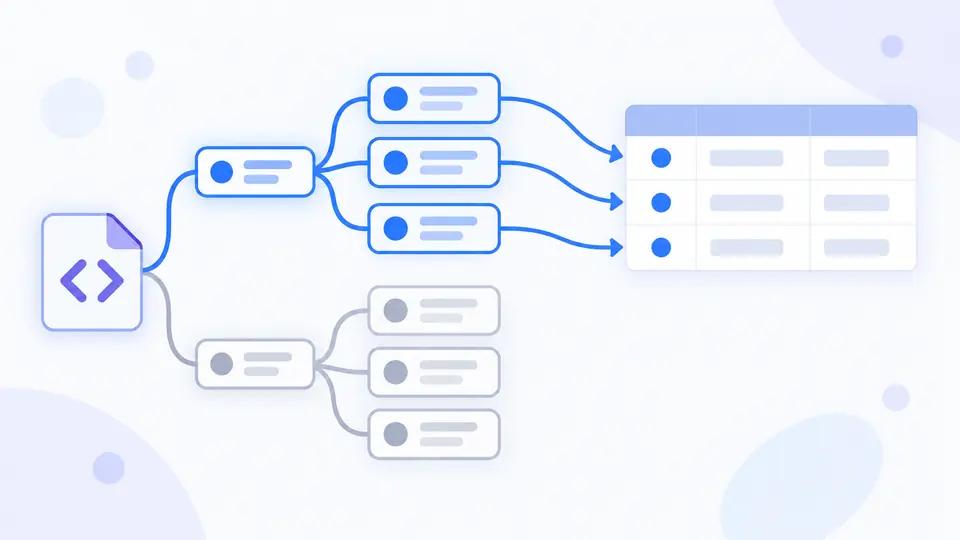
The suggested path uses repeated nodes. If two branches use the same tag, switch to the complete path and check its record count.
- A single record can also be selected manually.
XML / XPath / XSD
Choose a record path, inspect every column, and review any losses before export.
Processed in this browser. Your input is not uploaded or stored.
A product feed may contain two kinds of item node. An XML to CSV converter that guesses by tag name can quietly put archived entries beside current products. Here you choose the complete path before rows are made.
When the destination needs XML again, the same workbench maps CSV columns to elements, attributes, or record text. XML to CSV converter output remains a table extraction, not a promise that comments and mixed markup can be rebuilt.
The row definition and the missing data remain visible.
Two item branches can share a tag name. Select /orders/order rather than /archive/order, and the XML to CSV converter shows the row count for that exact path.
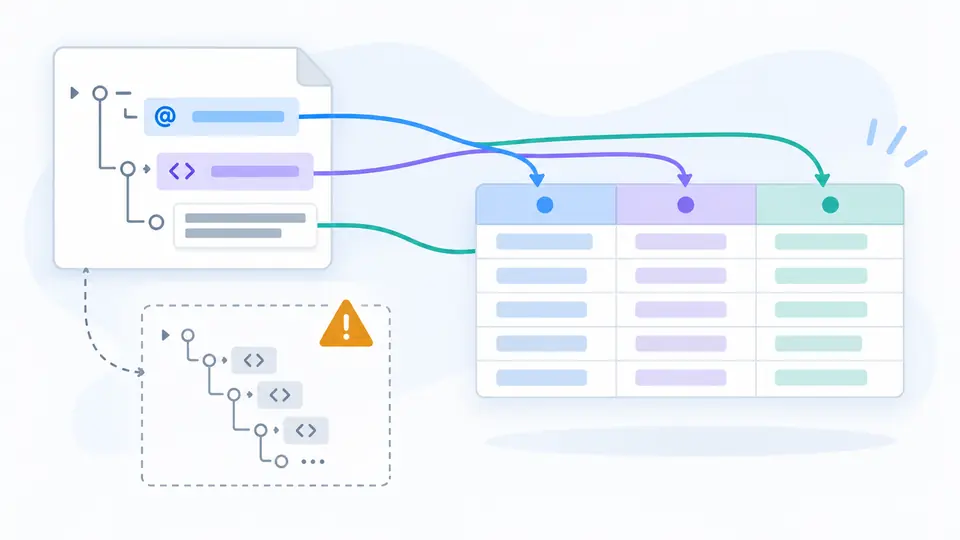
An ID in @id and a value in #text need different destinations. See the mapping and loss summary before treating a CSV cell as a faithful copy of XML.
The suggested path uses repeated nodes. If two branches use the same tag, switch to the complete path and check its record count.
Turn XML fields on or off and rename headers. In the reverse mode, choose element, attribute, or one record text column; invalid XML names need an explicit fix.
Repeated values, mixed content, and excluded fields are counted. Confirm a lossy result for this input and mapping before copying or downloading.
XML to CSV converter candidates show each repeated path with its count; similarly named nodes in other branches stay separate.
Flatten leaf text to dotted columns, include @ attributes, and rename or exclude individual CSV fields.
CSV to XML keeps values as strings and maps each header to an element, attribute, or one text slot.
Extract XML text in document order, or inspect omitted data before exporting a flattened CSV.
It suggests a repeated full path and lists candidate paths with counts. You may choose another path or a single record.
Yes. Keep attributes enabled; @id and a child named id remain separate column paths.
Nested leaf text becomes dotted paths. A repeated nested field or mixed markup is listed as a loss rather than silently merged.
The header is the union of fields found in the selected records; a missing field becomes an empty cell.
It is counted in the loss preview and not silently reduced to the first value. Choose a more specific record path when possible.
No. Parsing and export run in this browser; input is not sent to a conversion API.
Found an unexpected result?
Check the selected record path and any loss count, then copy or download the result.